Arthur Mensch Interview Breakdown: Key Insights on Open Weights, Chinchilla & AI Sovereignty
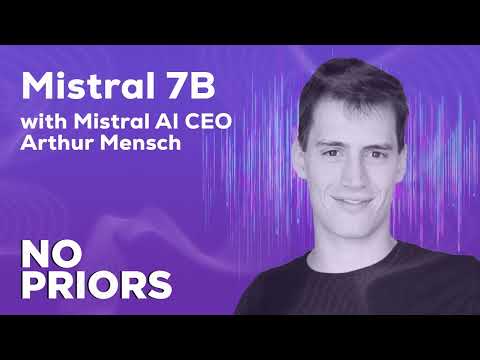
Arthur Mensch
Co-Founder & CEO, Mistral AI · Former Research Scientist at DeepMind
Lead author on DeepMind's landmark Chinchilla scaling law paper and co-founder of Mistral AI. Mensch is leading the European open-weight AI movement, pioneering highly efficient architectures like Mixture of Experts (MoE) and advocating for decentralized model sovereignty.
⚡ Executive Summary
- Breaking the Opacity Cycle in Frontier AI: Moving AI research behind proprietary corporate moats harms scientific progress; transparent open-weight models allow the global research community to collectively solve reasoning, steerability, and memory bottlenecks.
- The Chinchilla Overtraining Dividend: Scaling parameters for benchmark vanity is economically unsustainable; overtraining compact models (such as Mistral 7B) on high-quality data yields frontier intelligence with dramatically lower runtime inference costs.
- Architectural Efficiency with Sliding Window Attention: Implementing sparse attention mechanisms like Sliding Window Attention (SWA) and Grouped-Query Attention (GQA) dramatically reduces KV-cache memory footprints, maximizing token generation throughput on standard GPUs.
- Enterprise Sovereignty & On-Premises Control: True enterprise AI adoption requires private on-premises fine-tuning and weight ownership, preventing corporate IP leaks and vendor lock-in to US hyperscalers.
- Pushing Back on Compute Regulatory Capture: Arbitrary FLOP thresholds (such as (10^{26}) FLOP reporting limits) fail to track genuine safety risks while entrenching incumbents; regulation should govern downstream application risks rather than compute pre-conditions.
- Modular Safety vs. Monolithic Censorship: Foundation models should retain unrestricted knowledge of reality, while developers deploy modular, application-specific guardrails to filter undesirable inputs and outputs without crippling base model reasoning.
- The European AI Innovation Flywheel: Leveraging Europe’s elite mathematics and engineering talent, Mistral is building a sovereign European AI ecosystem to ensure technological independence and multi-polar AI governance.
📌 Timestamped Insight Cards
🔓 1. Breaking the Opacity Cycle: Why Open Science Outpaces Closed Monopolies [▶ @ 11:33]
“Around 2020, some companies started to be quite ahead on some field and realized that some value could be accrued, and then at that point opacity made it back to the field. That’s a cycle we’ve observed in software already: the cycle between openness and closeness. We think it’s too early and it’s really damaging for the science to move into such an opaque regime where you have a few companies basically doing the same thing, just not communicating about it… when in order to invent new techniques you need to still spend some large amount of money to actually try things at scale.”
Deep Insight: Mensch critiques the rapid walling-off of AI research by American tech giants. The breakthrough transition from basic deep learning models to modern LLMs was propelled by open academic collaboration and pre-print publishing. Premature corporate enclosure wastes immense global compute duplicating closed architectures while stalling foundational progress on unsolved challenges like long-horizon planning and causal reasoning.
⚡ 2. Chinchilla Scaling & The Inference Efficiency Dividend of Small Models [▶ @ 04:39]
“Chinchilla was pointing to the fact that you can actually train a model for longer with more data, and that this is actually optimal for compute… When you start thinking about deployment and enabling downstream applications, then you need to think about what it is going to cost in runtime… As a company that intends to have a valid business model, we think a lot about inference cost. We think that it’s super important to get to a regime where inference is super cheap so that you can run agents.”
Deep Insight: Optimizing purely for pre-training loss produces unwieldy, expensive models that fail commercial unit economics. By applying DeepMind’s Chinchilla scaling insights and extensively overtraining compact architectures on curated tokens, Mistral achieves GPT-3.5 tier performance at a fraction of the parameter count, drastically reducing latency and token costs for high-frequency agentic loops.
🏎️ 3. Sliding Window Attention: Architectural Innovations for High Throughput [▶ @ 29:20]
“To make serving efficient, there’s a lot of work to be done on the training side because you do need to come up with architectures that are memory efficient. For instance, that’s what Mistral 7B is good at, because it has this sparse attention mechanism that makes it more memory efficient… In order to reap all the benefits of a good model, you do need to work a lot on the inference part… to build a platform that will be very cost-efficient.”
Deep Insight: Standard multi-head attention scales quadratically with context length, bottlenecking GPU memory during high-concurrency inference. Mistral 7B introduced Sliding Window Attention (SWA), where each token attends only to a fixed window of preceding tokens while theoretical receptive fields propagate across deeper layers, slashing KV-cache RAM requirements and doubling serving throughput.
🏢 4. Enterprise Sovereignty: Fine-Tuning & Self-Hosting Private Models [▶ @ 10:31]
“If you look back at the history of machine learning in the last 10 years, it went very fast… We think that it’s important to provide models that can be fine-tuned, that can be customized, and that can be deployed on-premise… If you’re a large bank or healthcare provider, you don’t want to send all your proprietary customer data to a third-party API in California. Having access to model weights allows enterprises to truly own their intelligence infrastructure.”
Deep Insight: Relying exclusively on third-party proprietary APIs creates unacceptable compliance, operational, and data-privacy risks for regulated industries. Distributing portable, open-weight foundation models allows enterprises to fine-tune specialized models on proprietary internal data, maintain full cryptographic security on-premises, and guarantee operational continuity without vendor lock-in.
📜 5. Rejecting FLOP Thresholds: The Trap of Arbitrary Regulatory Capture [▶ @ 17:47]
“It’s very arbitrary, because who tells you that beyond that 10 to the 26 you end up with bad capacities, models start to see the emergence of bad behaviors? That’s definitely not proven. Relating capabilities to scale is also very approximate… We should really focus on capabilities and not pre-market conditions… and agreeing on what capabilities we deem dangerous… and not obviously pre-market conditions or the number of FLOPs that you do.”
Deep Insight: Mensch forcefully rejects regulatory proposals that attempt to govern AI safety by imposing arbitrary hardware training limits. Conflating cumulative training FLOPs with weaponization risk creates a dangerous regulatory moat that protects incumbent hyperscalers while outlawing open-source efficiency improvements. Sensible policy must evaluate empirical downstream capability risks rather than upstream compute budgets.
🛡️ 6. Modular Guardrails: Raw Foundation Models vs. Monolithic Censorship [▶ @ 23:15]
“The way you do it in our mind is that you do create the modular architecture that the application maker can use, which means you provide the raw model—so the model that hasn’t been altered to ban some of its output space—and then you propose new filters on top of that that can detect the output that we don’t want… Really assuming that the model should be well-behaved is I think a wrong assumption. You need to make the assumption that the model should know everything, and then on top of that have some modules that moderate and guard the model.”
Deep Insight: Hardcoding ideological censorship directly into model weights damages logical coherence and renders models useless for content moderation or cyber defense. Mistral advocates for modular system architecture: training uninhibited base models that comprehend the full spectrum of reality, while providing separate, composable guardrail modules that application developers can customize to enforce safety constraints.
🇪🇺 7. The European AI Flywheel: Mathematical Talent & Sovereign Innovation [▶ @ 31:05]
“A very strong point of Europe on that domain is talent. As it turns out, France, UK, Poland are very good at training mathematicians, and as it turns out mathematicians are very good at making AI… Today we have hundreds of startups in Paris… It’s the same kind of flywheel that made San Francisco and the Bay Area successes is starting to spin in France, and I’m very glad that we’re participating to it.”
Deep Insight: Europe’s world-class academic institutions produce an elite surplus of mathematicians, physicists, and machine learning researchers. By anchoring Mistral in Paris, Mensch is constructing a self-sustaining innovation flywheel that retains European technical talent, fosters venture capital deployment, and ensures global AI development is not dictated by a Silicon Valley monoculture.